 Physix Frontier
Architectural Breakdown of Wenge's Decision Intelligence Line: Deployment Is Harder Than Expected

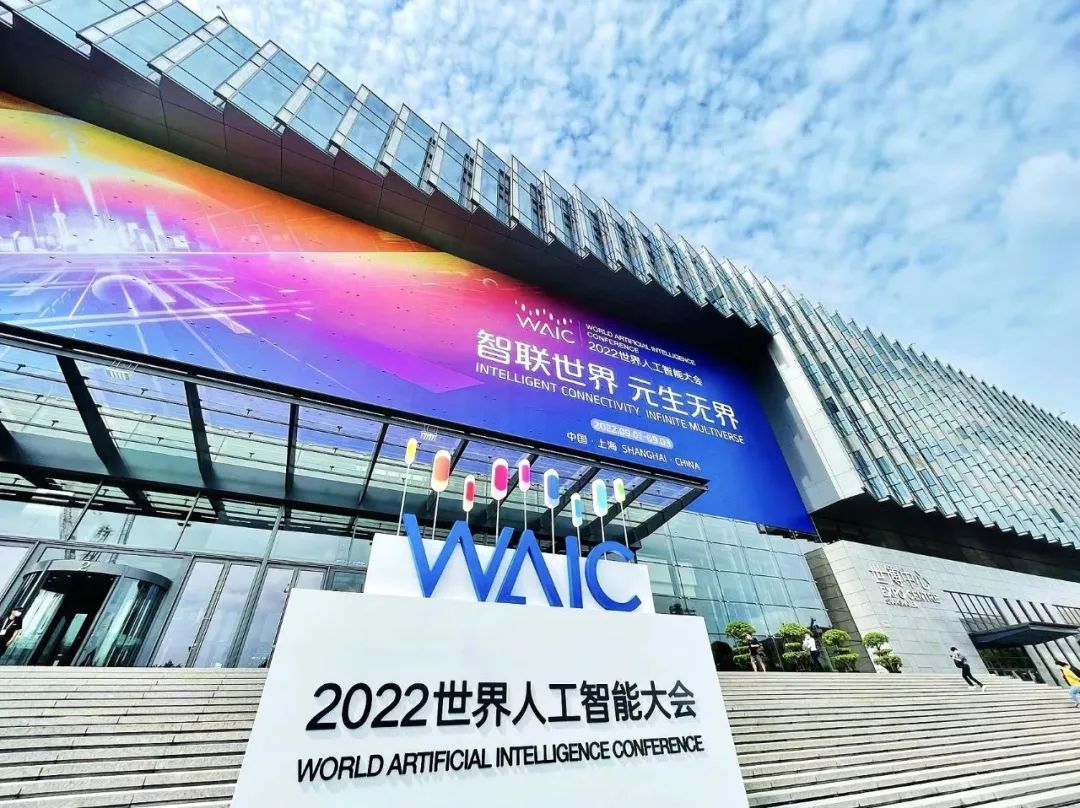
At the 2026 World Artificial Intelligence Conference, Wenge (Zhongke Wenge) released five products all at once: the DIP Decision Intelligence Platform, TokSea, Claworks Dragon Worker Agent Platform, Panshi Scientific Research Foundation Large Model, and Decitron Decision Machine. On the surface, this looks like completing a product matrix, but as a backend architect, I care more about the engineering costs and scalability risks behind these products.
Let's look at some data: According to Wenge's official info, the Decitron Decision Machine claims to achieve a closed loop of "reasoning + prediction" across multiple industry scenarios, keeping inference latency under 200ms and supporting millions of daily decision requests. TokSea is positioned as a multimodal data fusion platform, claiming to handle 12 types of data including structured, unstructured, and time-series. These numbers sound pretty, but when deployed in actual production environments, every minor detail could become a bottleneck.
From an architectural perspective, Wenge's product line hits the core contradiction of current AI implementation: Large models have "understanding" capabilities but lack "decision-making" capabilities. Many companies buy large models only to find they can only do chatbots and document summaries. When they actually need supply chain optimization, risk pricing, or resource scheduling, the models can't provide executable solutions. Wenge tries to fill this gap using the "Decision Machine" middleware. The idea itself is correct, but there are several key trade-offs in engineering implementation.
The first problem is data pipeline heterogeneity. TokSea needs to handle 12 data types, meaning the underlying storage system must simultaneously support vector databases, time-series databases, graph databases, and traditional relational databases. This multimodal storage architecture works fine in demos, but once in production, data consistency, query latency, and operational complexity rise exponentially. I've seen too many teams stumble on "multimodal fusion," eventually retreating to the clumsy "data lake + ETL" approach. If Wenge cannot provide a clear solution for data synchronization and transactionality, this platform's scalability will be problematic.
The second problem is the promise of decision latency. A 200ms inference latency sounds excellent, but remember the Decision Machine sits on top of large models. If the underlying call is to the Panshi Scientific Research Large Model, a single inference by the model itself might take 500ms. Add the middle layer's rule engine, knowledge graph queries, and multi-turn strategy orchestration, and 200ms is basically impossible. Unless the Decision Machine does heavy pre-computation and caching, pruning for high-frequency scenarios. But this means the Decision Machine can only handle limited categories of structured decisions and will have poor adaptability to dynamically changing business scenarios (like real-time e-commerce pricing).
The third problem is the positioning of the Claworks Dragon Worker Agent Platform. An agent platform is essentially a low-code orchestration tool, allowing business personnel to build decision flows via drag-and-drop. This design lowers the usage barrier but sacrifices flexibility. Real business decisions often require complex conditional branches, loops, and exception handling, which low-code platforms struggle to support. From an architectural standpoint, I prefer viewing agents as "development frameworks" rather than "platforms," providing APIs and SDKs for engineers to call directly, rather than using visual interfaces to limit expressiveness.
Back to actual implementation. Wenge's customer base is mainly government, finance, and scientific research institutions. These scenarios feature sensitive data, high compliance requirements, and complex deployment environments. For the Decision Machine to succeed here, it must solve the disconnect between offline training and online inference. Many decision systems perform well in offline evaluation after launch, but accuracy collapses immediately when online data distribution shifts. In Wenge's product line, the DIP Decision Intelligence Platform handles data cleaning and feature engineering, while Decitron handles real-time inference. There is a lack of a closed-loop feedback mechanism between them—for example, how online error data automatically flows back to the training set and triggers model retraining. Without this loop, so-called "decision intelligence" is a one-off.
I noticed Wenge repeatedly mentions "industry Know-how" in press releases, which is a very pragmatic statement. Compared to big tech's general-purpose AI platforms, Wenge's advantage lies in deep cultivation of vertical industries, such as financial risk control, public opinion analysis, and scientific research assistance. Decision logic in these scenarios often has clear rules and boundaries. Using large models for "reasoning" is actually doing a mix of "rule matching + probabilistic prediction." If the Decision Machine can tightly integrate rule engines and statistical models, it finds a differentiated position in the era of large models.
However, the core risk lies in the coupling degree of the tech stack. The Panshi Scientific Research Large Model, TokSea, DIP Platform, Decitron, and Claworks—if these five products depend too deeply on each other, an upgrade in any single component could cause overall service interruption. Architecturally, they should adopt a "microkernel + plugin" design, letting the Decision Machine act as an independent inference engine capable of connecting to any large model and any data source. Currently, Wenge's product line looks more like a "full suite," where users must buy everything if they want any part, violating the basic requirement of "replaceability" in enterprise software.
Finally, an action suggestion: If your company is considering introducing decision intelligence products, try a small-scale POC first, focusing on testing three dimensions—fault tolerance of data ingestion (does the system crash when data formats change?), stability and explainability of decision results (can it provide decision basis rather than being a black box?), and scalability (how do latency and cost change when business volume doubles?). Don't be misled by concepts like "full suite" and "decision intelligence." What actually runs in production is often the least sexy part of the engineering details.
Wenge's move is correct, but how fast and how far they go depends on whether they can find a balance between "engineering complexity" and "business value." For technical teams, instead of chasing the sexy concept of "decision intelligence," better to get your data pipelines and model monitoring systems right first—that is the cornerstone of all intelligent decision-making.
Original link: https://www.leiphone.com/category/industrynews/d6jcZEDt7SPlnwhh.html